Melanie Smith
VP OF SALES DEVELOPMENT @ NOOKS
Melanie Smith is VP of sales development at Nooks, leading outbound pipeline growth, hiring, coaching and AI execution.

VP OF SALES DEVELOPMENT @ NOOKS
Melanie Smith is VP of sales development at Nooks, leading outbound pipeline growth, hiring, coaching and AI execution.

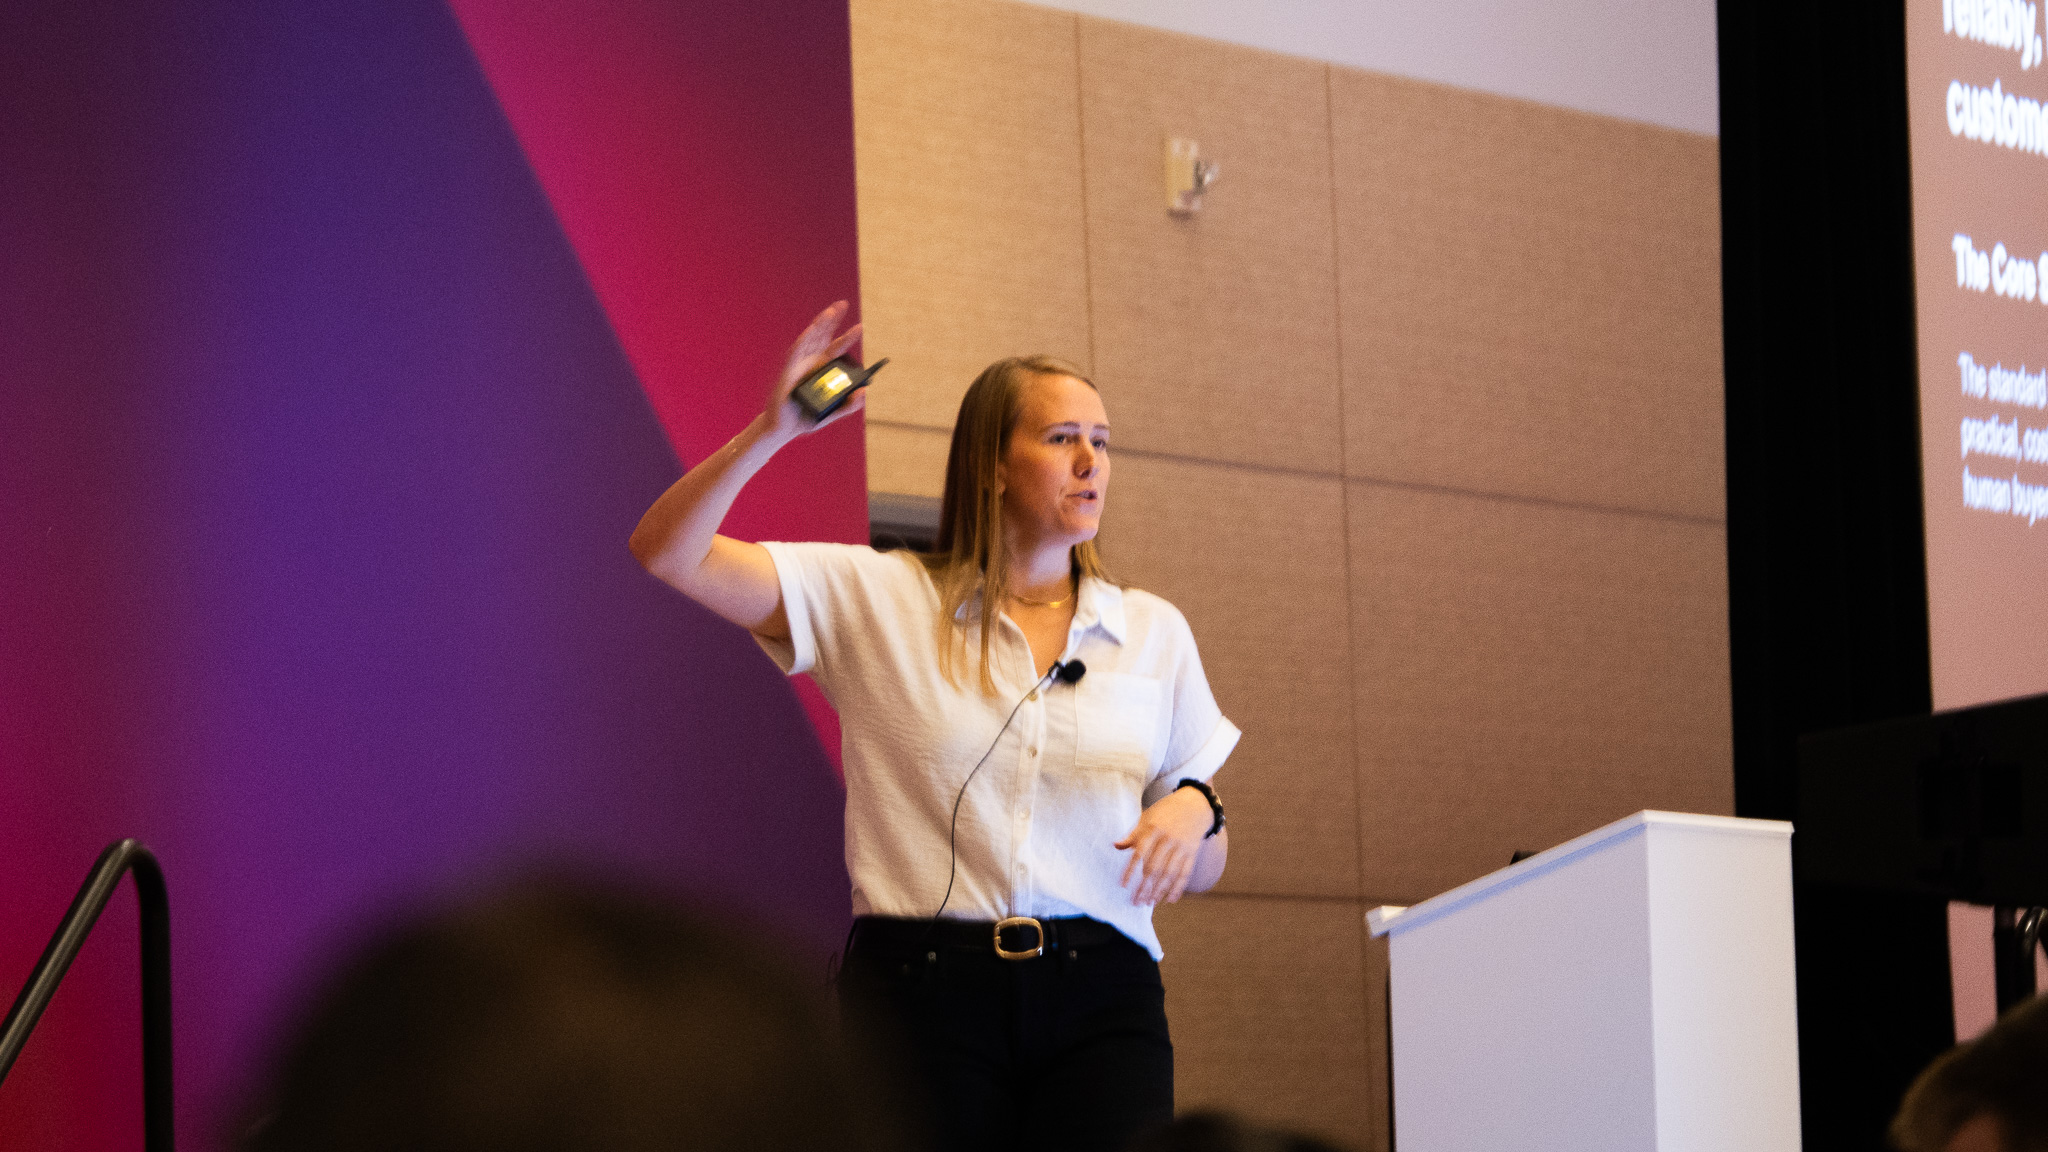
Melanie, VP of Sales Development at Nooks, opened with a question rather than a claim: who in the room could say, in dollars, how much pipeline their AI had generated? Very few hands went up. It was a deliberately uncomfortable start to a thirty-minute argument built on what Nooks has observed across more than a billion sales interactions — that the problem in most go-to-market teams is no longer the technology, but the absence of an operating model telling anyone how to use it.
The premise is levelling: budget aside, most teams have access to broadly the same models and broadly the same tooling. The software, she argued, is frequently better than the way it is being used. That reframes the buying decision entirely. The differentiator is not the vendor on the contract, it is whether a team has done the unglamorous work of deciding — task by task — what the machine owns, what it assists with, and what it must never touch.
"It's not necessarily about what software you buy or what vendor you choose, but more specifically, did you take the time to put together an operating model of exactly how it will be used?"
She was explicit about scope: this was not a session about measuring ROI. It started earlier than that — at the baseline map you should hold before you buy or deploy anything, so you can answer the simplest question of all: what, precisely, is this tool being bought to do?
The pattern she described will be familiar to anyone who has bought AI in the last two years: buy the tool, deploy the tool, hope it works, and find out how it went roughly twelve months later. It is not negligence so much as optimism at scale — the assumption that capable people handed capable software will converge on good practice by themselves.
Her own cautionary tale made the point better than any statistic. Around ten to twelve months ago, an enterprise SDR on her team bought a personal ChatGPT Enterprise licence and reported significant gains. Within a week, twelve more enterprise SDRs asked for the same. She bought thirteen licences — and issued no guidance whatsoever.
"I bought 13 licences… and I gave them no map. I just said I trust you."
Two months later she asked her team how, when and why they were using it. The audit was sobering: roughly half had logged in a couple of times and drafted a few emails; four reps had used it for personal matters — plant care, cooking recipes; and only two had built something genuinely useful and repeatable that the wider team could adopt. Trust was not the missing ingredient. Definition was.
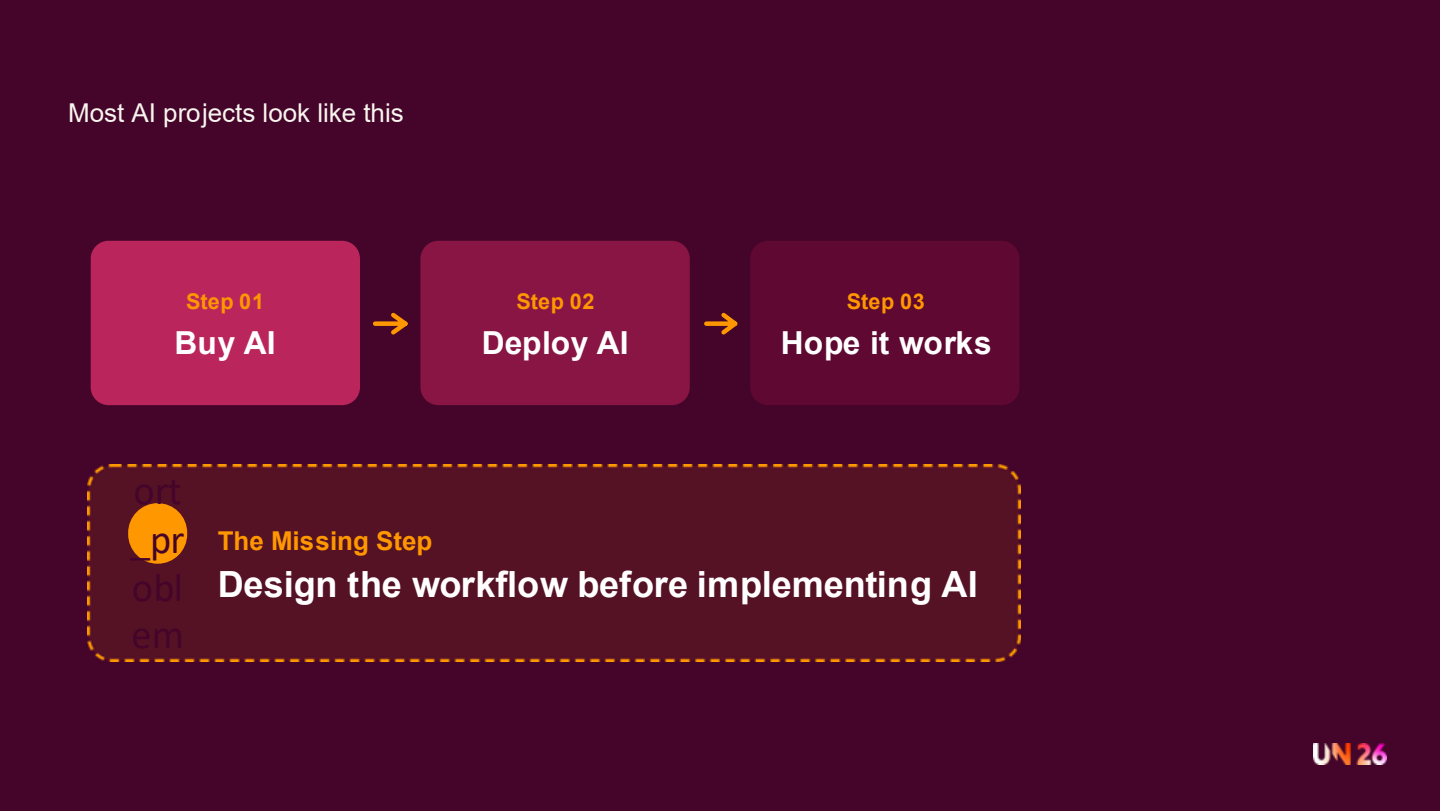
The corrective is not an AI policy document, and it is not a centralised subject-matter-expert squad. Both arrive too late. The map has to exist before the technology is purchased, and it has to be granular. "Automate prospecting" is far too coarse an instruction to act on; the recurring tasks inside prospecting have to be pulled apart and assigned individually.
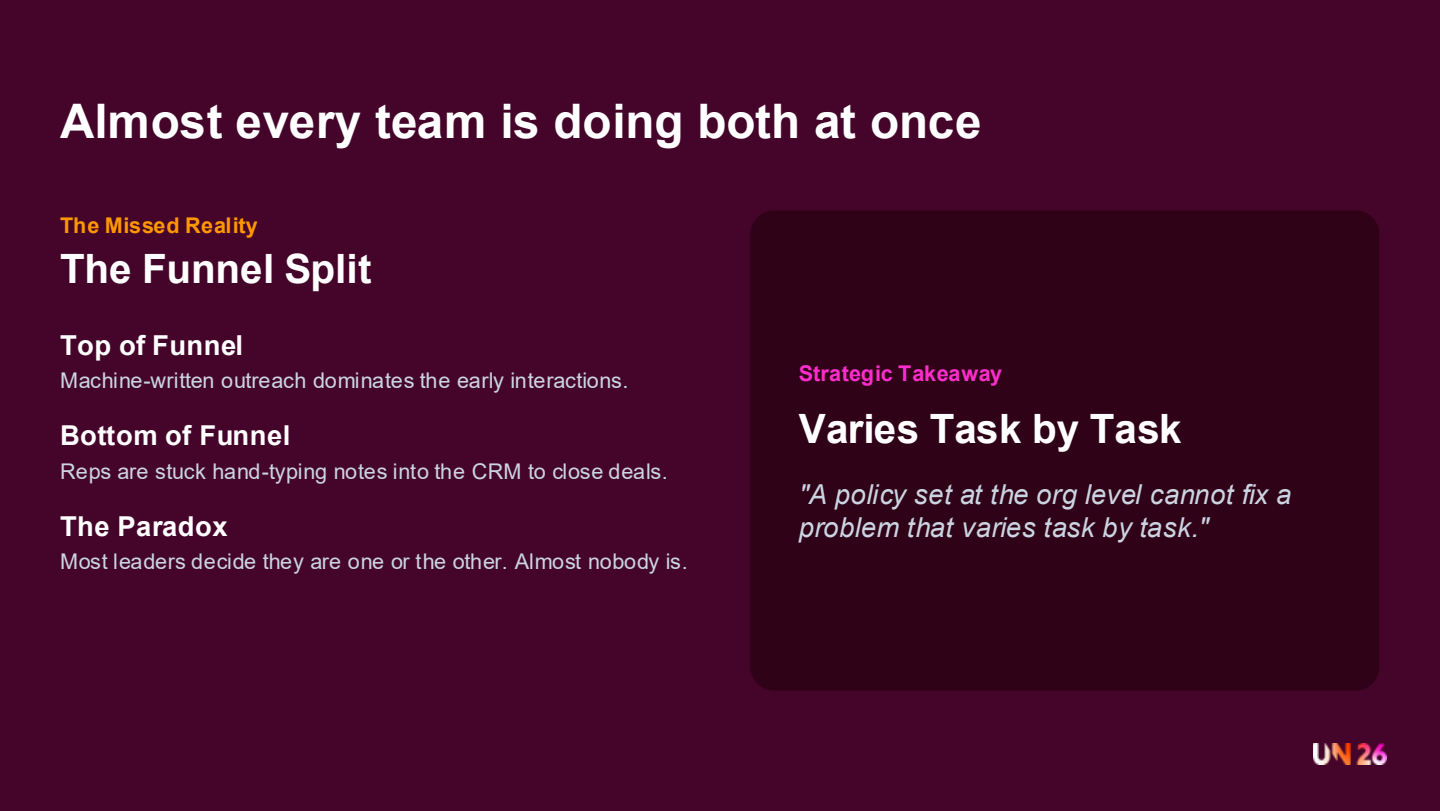
The first camp over-automates. Sales engagement gets switched to automatic, send volume rises roughly tenfold, reply rates fall and domains get burned. The visible symptom is the hyper-"personalised" email referencing a LinkedIn post the prospect never actually wrote. But the expensive damage never appears on a dashboard: talent development. If a rep cannot work out for themselves why an account matters, they are unlikely to run good discovery later.
"If a rep cannot figure out why an account matters, they probably aren't going to be able to do very good discovery."
The second camp under-uses. The tool is bought, adoption stalls near 20%, and the executive team starts asking about pipeline generated and deals influenced — while reps still spend the bulk of their week on CRM notes and account research. Ask those reps how, when and why they use the tool and the honest answer is "I don't know". That is not resistance, she argued; it is the absence of a map. And operationally, "I don't know" means they are not using it and do not intend to.
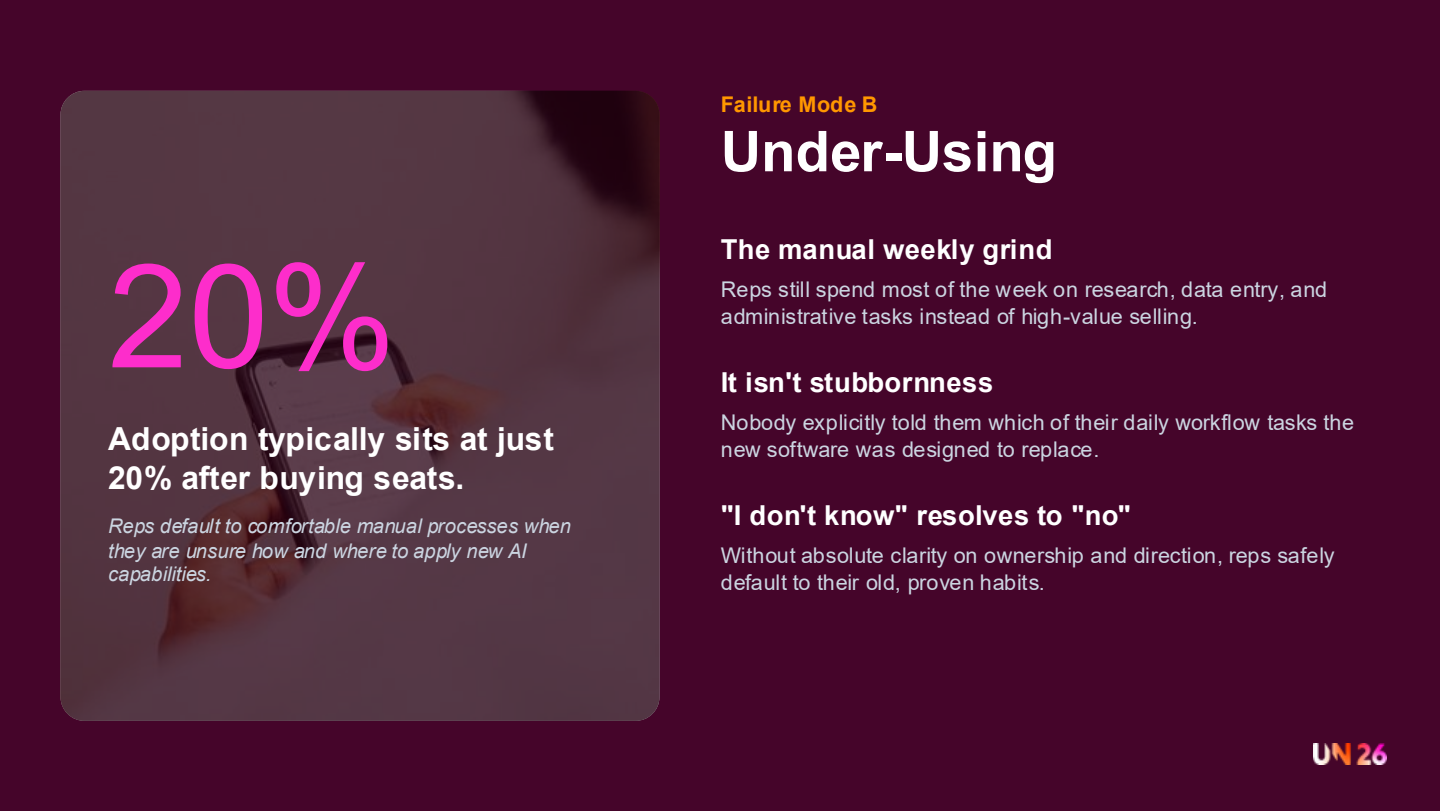
The under-use camp in one number: tooling bought, adoption stuck around 20%.
The most overlooked point of the whole session followed: most teams are doing both at once — sometimes inside the same workflow. Which is exactly why the decision cannot be made at workflow level. A quick diagnostic she offered: ask three reps how, when and why they use a given tool. If none of them can give you a straight answer, there is a missing piece and it is worth investigating before anything else.
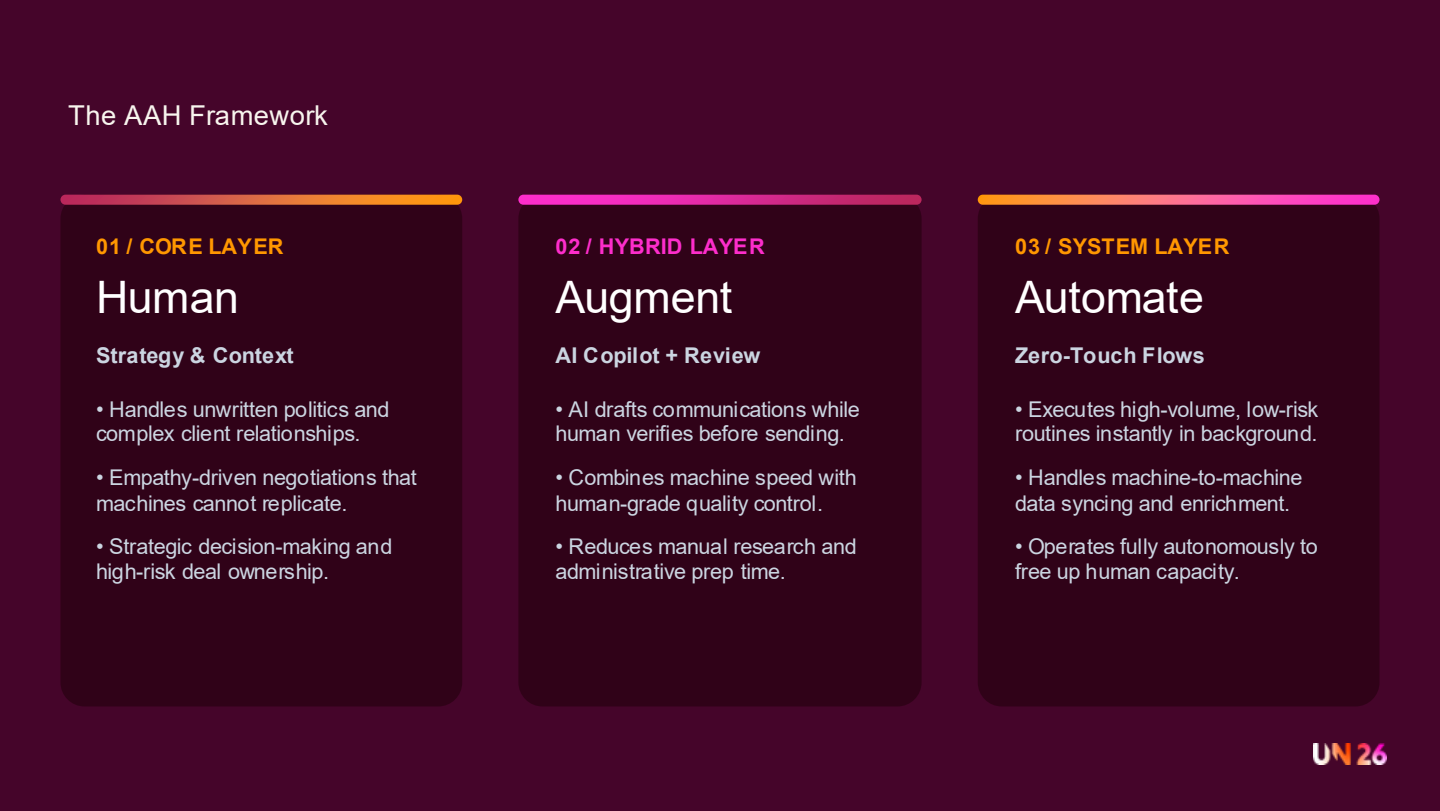
The framework itself is deliberately small enough to hold in your head. Every recurring task in the sales motion belongs in one of three buckets. Automate means the machine owns the task end to end; a human may audit samples to confirm the model is behaving, but should not be reviewing every instance. Augment means the machine does roughly the first 80% and the human decides and ships — the human is always the last step. Human-only means the machine must not touch the interaction at all: it may prepare, but it must not perform.
She was pointedly critical of "human in the loop" as a phrase. Given where the technology now sits, it is too vague to be useful; the distinction that matters is between automate and augment. And automation carrying a token review stamp is not automation at all. A rubber-stamp tick box signals that you do not trust the system, and it quietly loads the rep with guilt and overhead while delivering none of the time saving you bought.
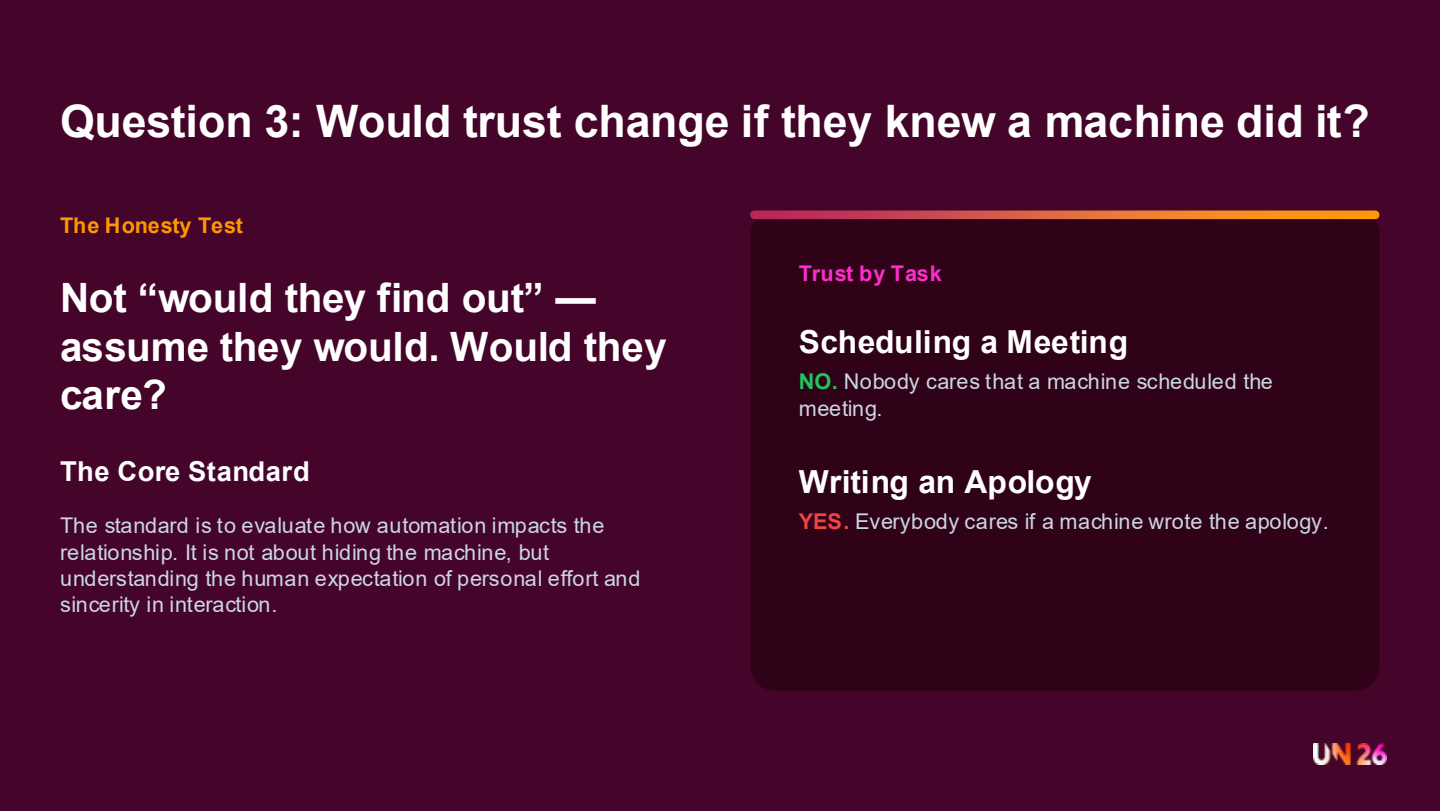
Underpinning all of it is a simple observation about the market: sales is still human to human. Buyers do not care whether a machine booked a follow-up meeting. They care very much if a machine wrote an apology note.
Assignment to a bucket is not a matter of taste. Three questions, asked in order, do the sorting.
The scoring rule falls out neatly. Verifiable, no hidden context and not trust-bearing means automate. A "yes" on hidden context, but the machine can still draft something for the rep to decide on and execute, means augment. Trust-bearing — or a mistake you simply cannot take back inside a relationship — means human: the machine preps, it does not perform, and you protect that moment.
"Automate the input, augment the judgement, but still protect the moment."
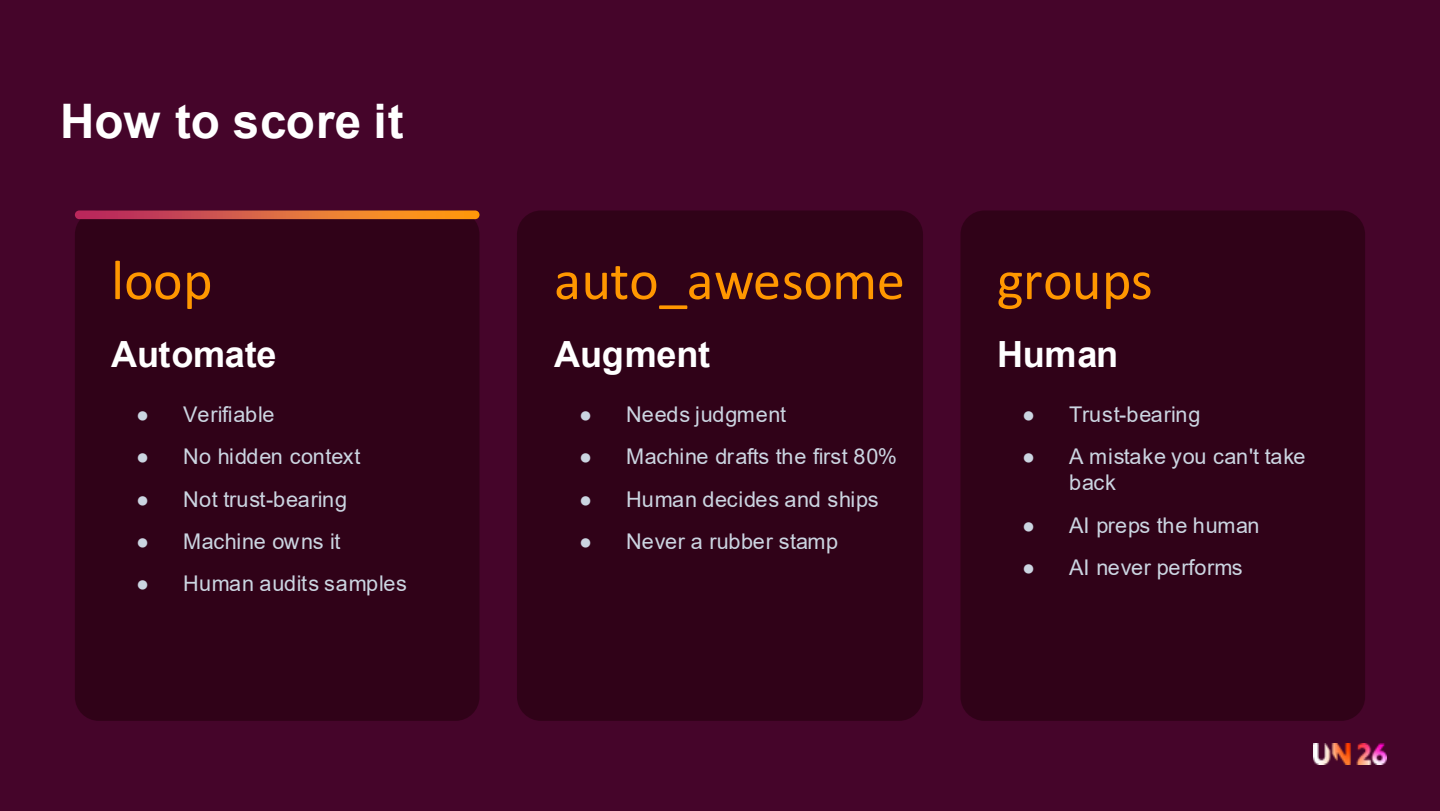
As the leader of Nooks' sales development team, she admitted that twelve months ago the easy line was: automate prospecting entirely, and let reps spend 100% of their time cold calling. She no longer believes that is realistic. Reps still have to make decisions, tweak emails and retrieve context — the conversation at an event, the detail that never made it into a field.
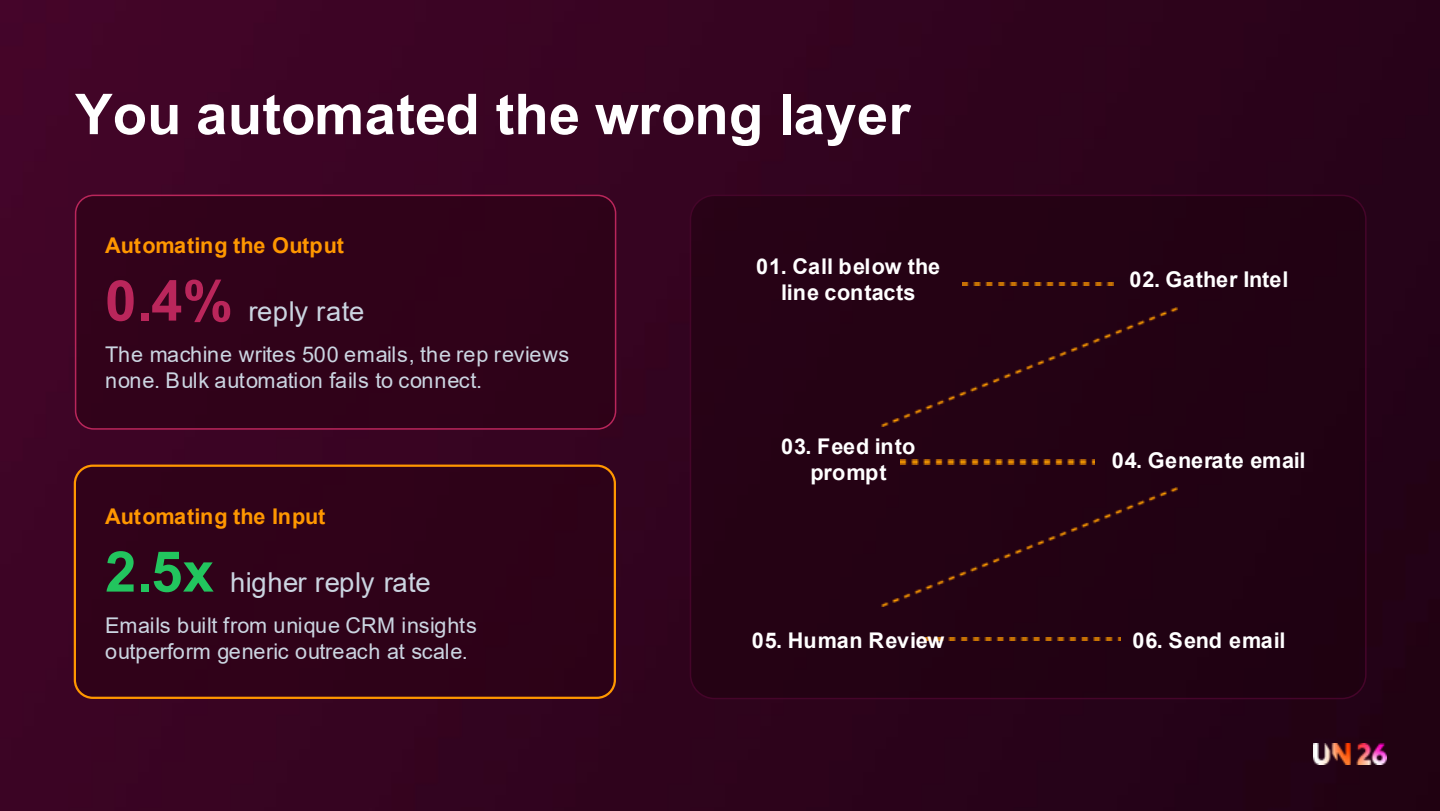
The most common mistake is not simply automating too much. It is automating the wrong layer. Teams automate the output — the mass AI email, the slop currently filling LinkedIn feeds and inboxes — when they should be automating the input: account research, briefs, everything the system reads and assembles. The email itself belongs in augment, where a human reads it and confirms it actually fits what is known about the account and the prospect.
The worked comparison was stark. Over-automate and the machine writes 500 emails at a 0.4% reply rate — not worth the domain damage. Flip the layer and the machine produces 500 research briefs while the rep writes 40 context-rich emails, at a materially higher response rate. Same hours, same head count, considerably better results.
Run the same exercise over sales engagement and the automate column fills up with pure administrative overload. Her line on this was blunt: there is no craft in typing call notes into a CRM. She confessed to having previously insisted that SDRs hand-write every call note, and now regards that as a waste of time — systems can listen to the call and draft the note, with the SDR reviewing rather than transcribing.
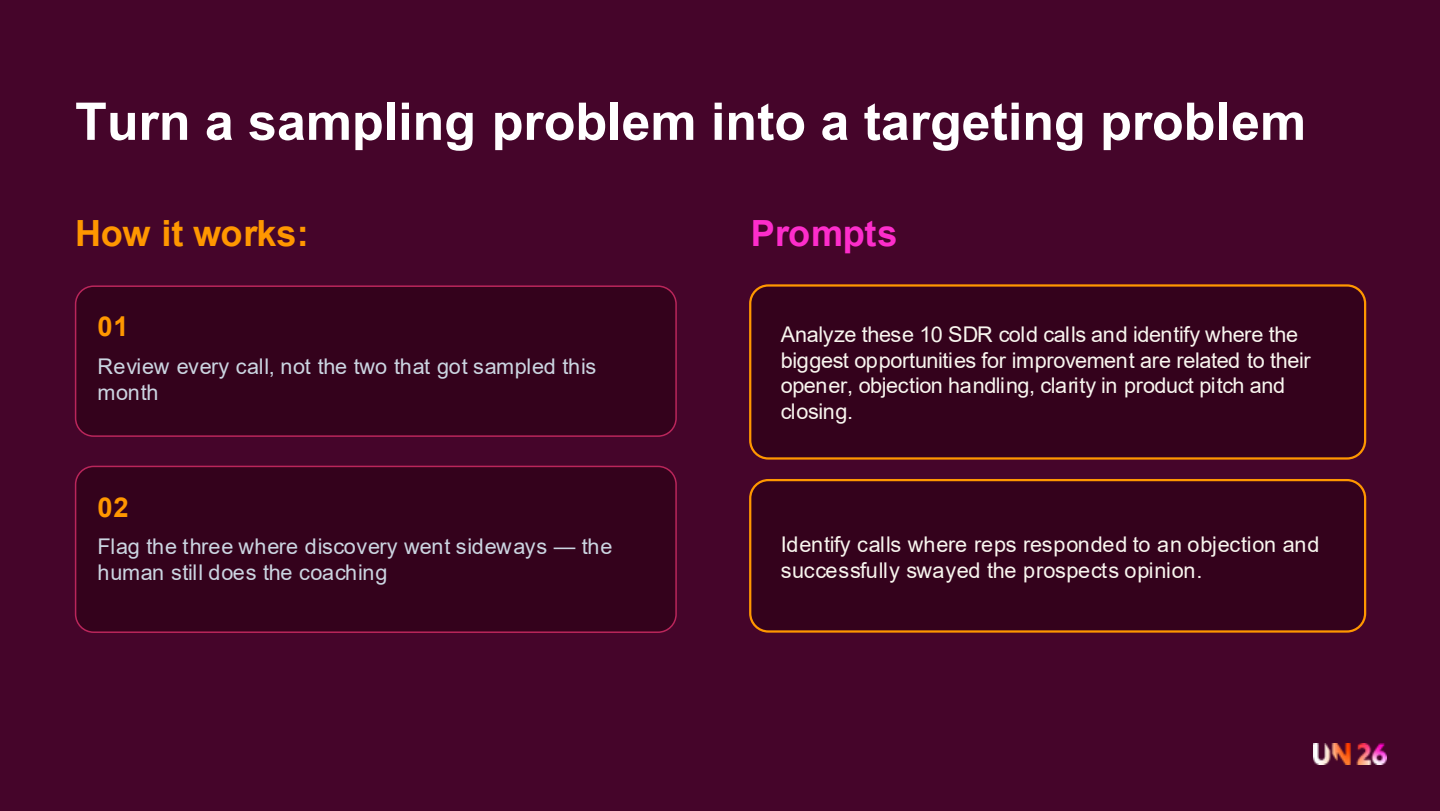
Call scoring, by contrast, sits firmly in augment. She has watched both extremes: managers who insist on listening to every single call, and teams who hand the judgement entirely to a scoring tool. Her position is that AI should score all calls and surface the patterns, but the human delivers the coaching — tailored to each rep's style — and owns the development plan. The machine turns a sampling problem into a targeting problem; it does not turn a manager into a coach.
"AI can't coach."
She also stressed that bucket allocation is company- and segment-specific. Enterprise and SMB motions carry very different volumes, and what belongs in automate for one will sit in augment for the other. There is no portable answer key — only the task-by-task breakdown.
Late-stage deal management, on the AE and AM side, is where the three questions all come back "yes". You cannot verify the work before the buyer feels it. The context is unwritten and lives in small interactions rather than transcripts. And trust is the entire asset — as she put it, a lot of the time people buy from people they trust; if they didn't, there wouldn't be sales people.
So late-stage buyer interactions do not get automated. The machine's job shifts to preparation and to surfacing what the rep would not otherwise know: what was shared during a prospect's previous evaluation, or a leadership change visible online that nobody caught on LinkedIn. Prep your AE before they walk into the meeting — and then protect the moment itself.
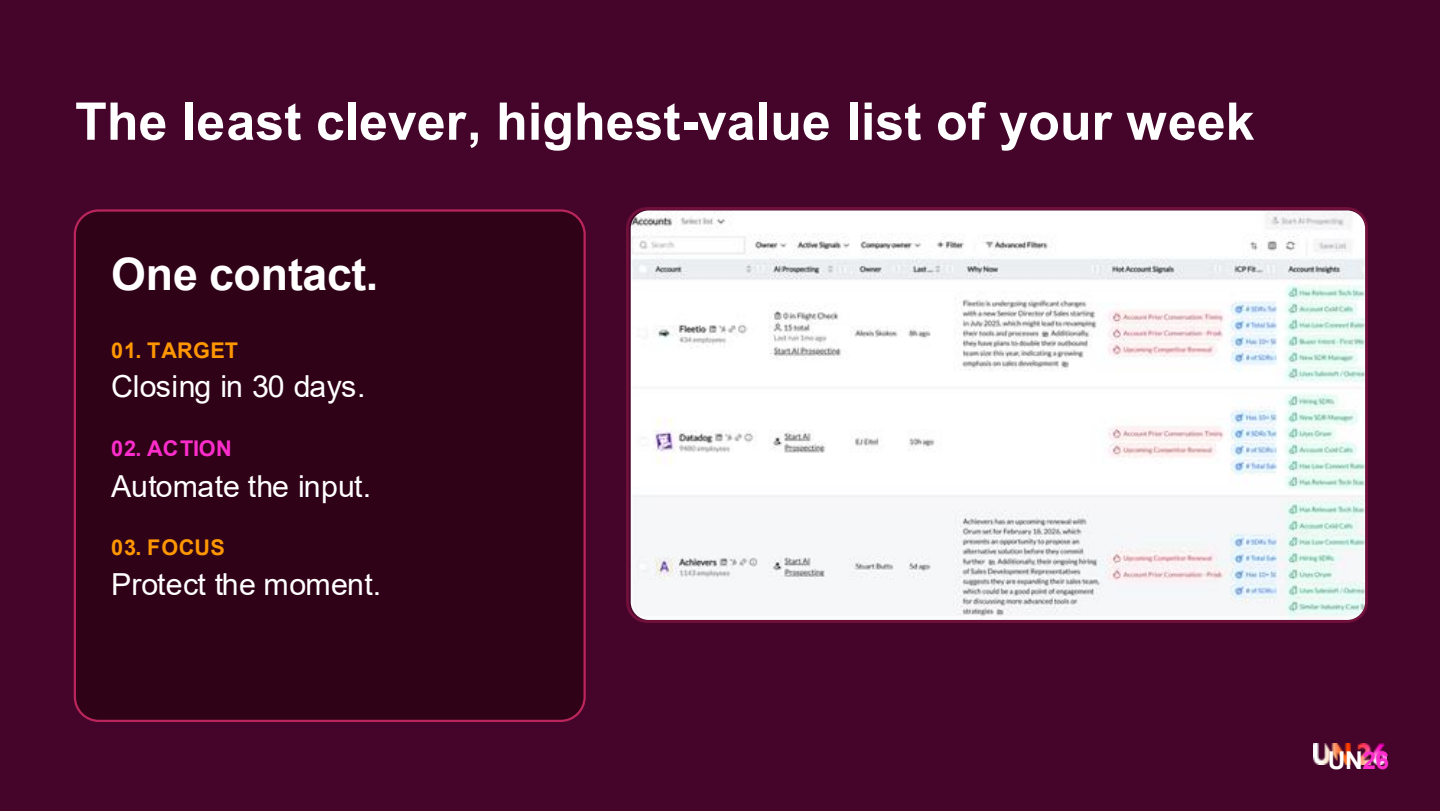
There is a second, quieter role for AI here: directing where humans spend their time. Nooks does this internally by pulling every deal with only one contact and a close date inside the next 30 or 60 days — adjust the window to your own deal cycle — and using that list to set the focus for the month or the quarter. It is not clever. It is arguably the least clever, highest-value list of the week. And the machine cannot do the follow-up: the second outreach and looping in additional stakeholders are human actions.
The closing section was explicitly tactical, and explicitly anti-strategy-document. Do not build a strategy. Do not convene a working group. Do not write a quarterly or annual plan to fix everything. Instead, spend an afternoon — of which roughly one hour is sitting with a rep.
The tasks people classify as automatable are, she warned, usually embarrassingly obvious. The value is not in the obvious entries; it is in the mismatches — the things everyone assumed were automated that should have been augmented. Outbound email is the recurring example: not all of it should be automated, so some of it needs reclassifying.
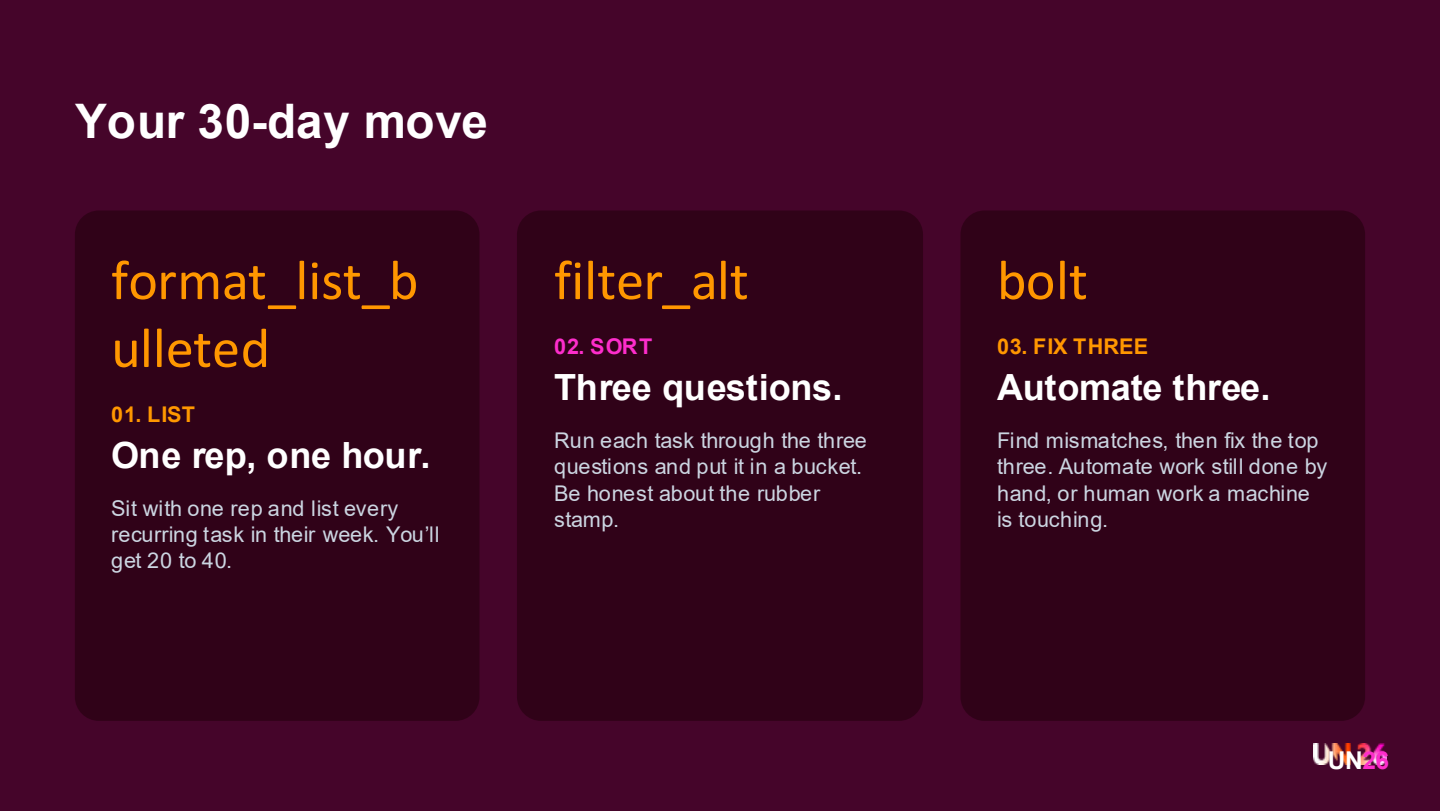
Then comes the discipline. From a list of 20 to 40 items, choose three — probably the easiest, most obvious three. Nobody can fix everything at once, and everyone in the room has a full-time job on top of working out where AI fits. The same lens should be pointed at technology already purchased and poorly adopted, as well as anything currently under evaluation. Target execution window: the next 30 days.
"Things need to be bite sized and not just added to a list. If you have a list of 20 to 40, choose three."
One question was taken at the close of the session.
What kind of feedback loops do you need in place?
It depends on what you are automating versus augmenting, and on the technology you already have — some tools ship with strong reporting built in. The non-negotiable is that some form of feedback loop exists before you start, not after. She cited A/B testing as one practical approach: with a team of around 40 reps, have some trial one approach and others trial the alternative. How you operationalise that will vary with team size.
The three questions were left on screen for attendees to photograph, and she invited anyone with examples or bucket-classification queries to continue the conversation at the booth downstairs.