Melanie Smith
VP OF SALES DEVELOPMENT @ NOOKS
Melanie Smith is VP of sales development at Nooks, leading outbound pipeline growth, hiring, coaching and AI execution.

VP OF SALES DEVELOPMENT @ NOOKS
Melanie Smith is VP of sales development at Nooks, leading outbound pipeline growth, hiring, coaching and AI execution.
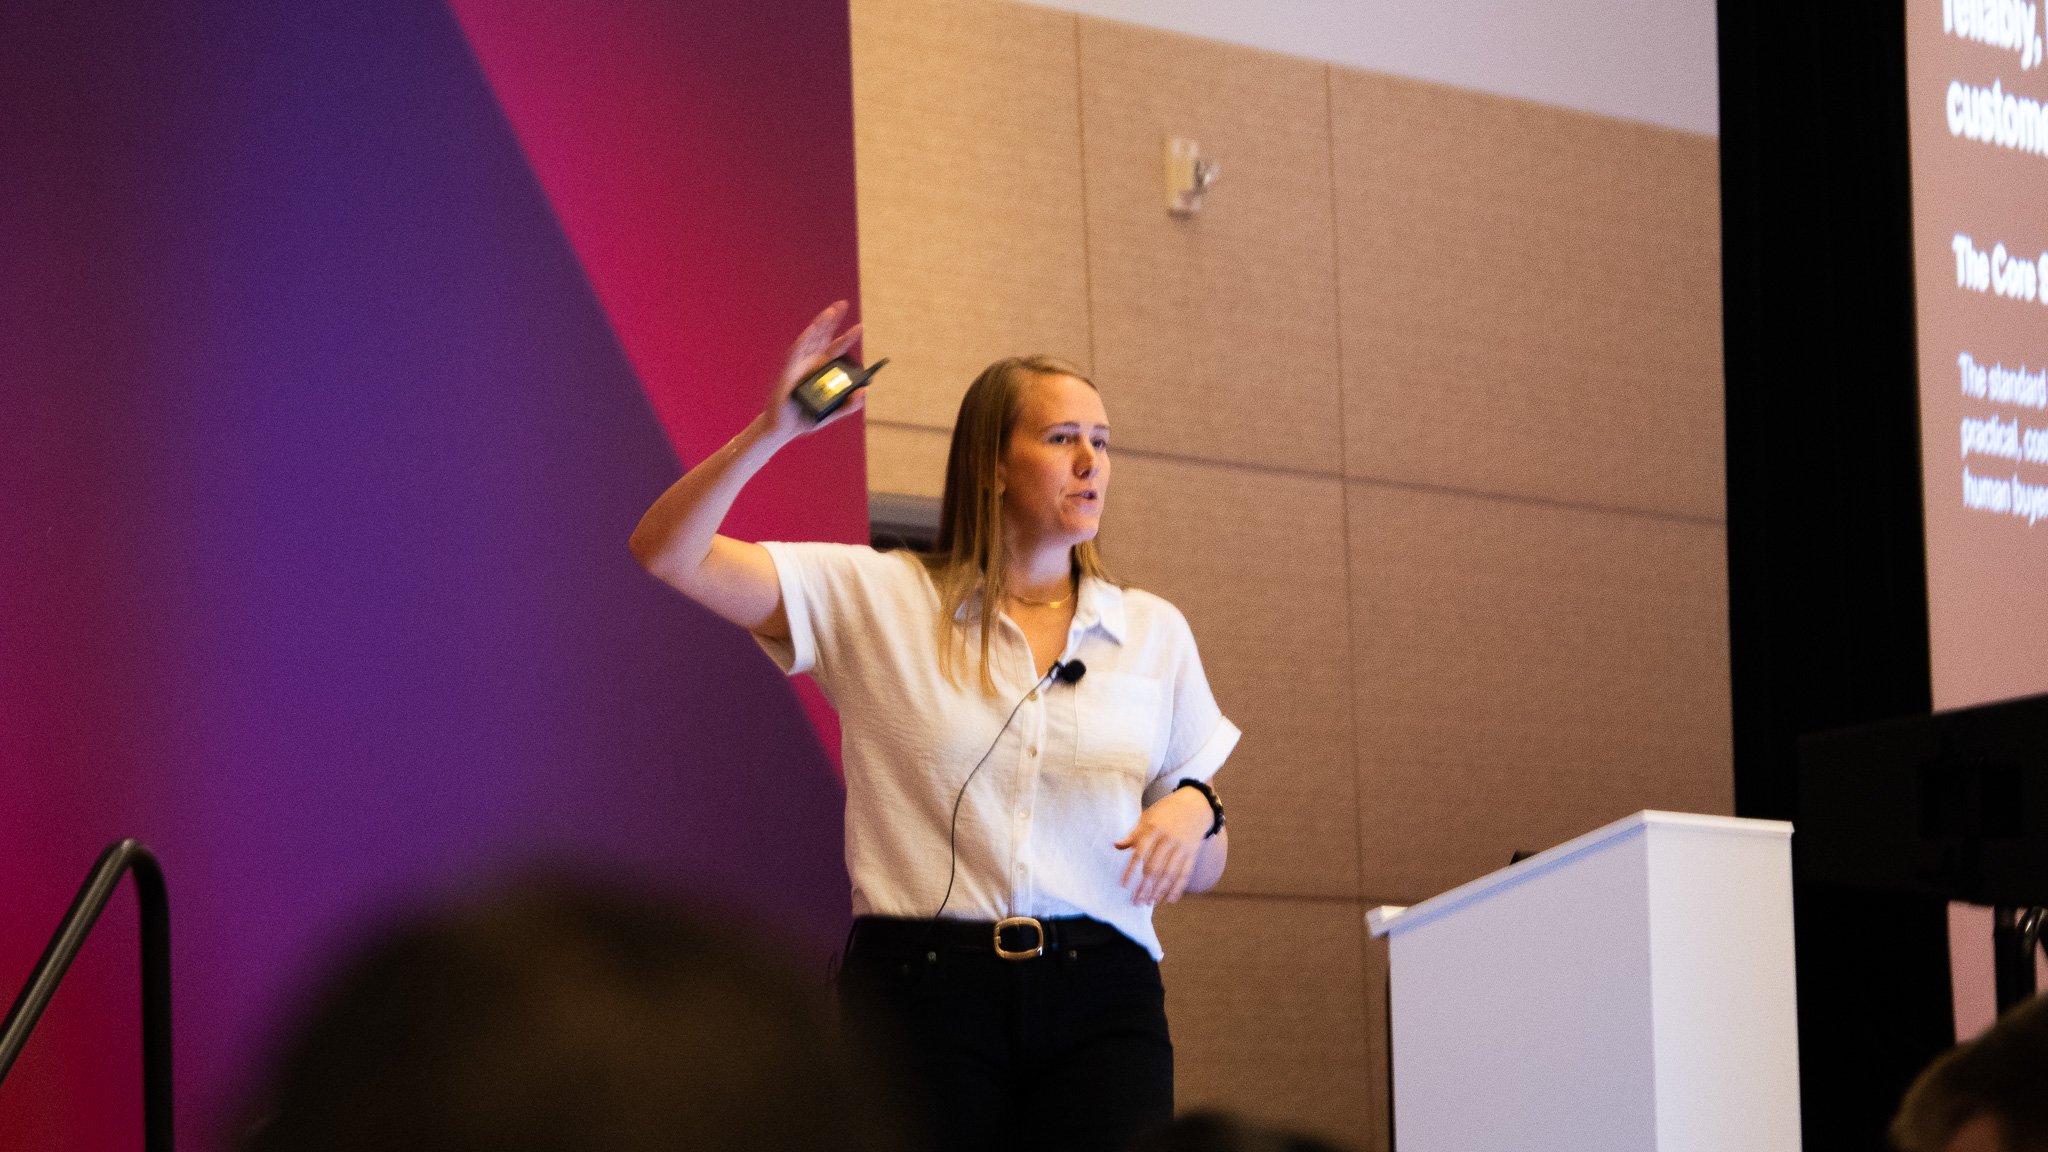 Melanie SmithAutomation Isn’t Strategy: Rethinking AI in Sales

Melanie Smith, VP of Sales Development at Nooks, opened her session with a question rather than a claim: how many people in the room could say, in dollars, how much pipeline their AI had actually generated? Very few hands went up. That silence became the spine of a thirty-minute argument that had almost nothing to do with vendors and almost everything to do with discipline. Nooks has observed more than a billion sales interactions through its platform, and the pattern Smith drew from that data is uncomfortable: the technology is probably better than the way most teams are using it.
Her thesis is deceptively simple. Everyone has access to broadly the same models. Differentiation therefore cannot come from the logo on the invoice. It comes from whether a team has built an operating model that defines, task by task, where the machine runs the work, where it assists, and where it must not touch the interaction at all. "I'm going to automate prospecting" is not a strategy; it is a sentence that hides twenty or thirty separate decisions.
This session deliberately did not cover ROI measurement. It offered something arguably more useful upstream of ROI: a decision map, three screening questions, three buckets, and an exercise that fits into a single afternoon.
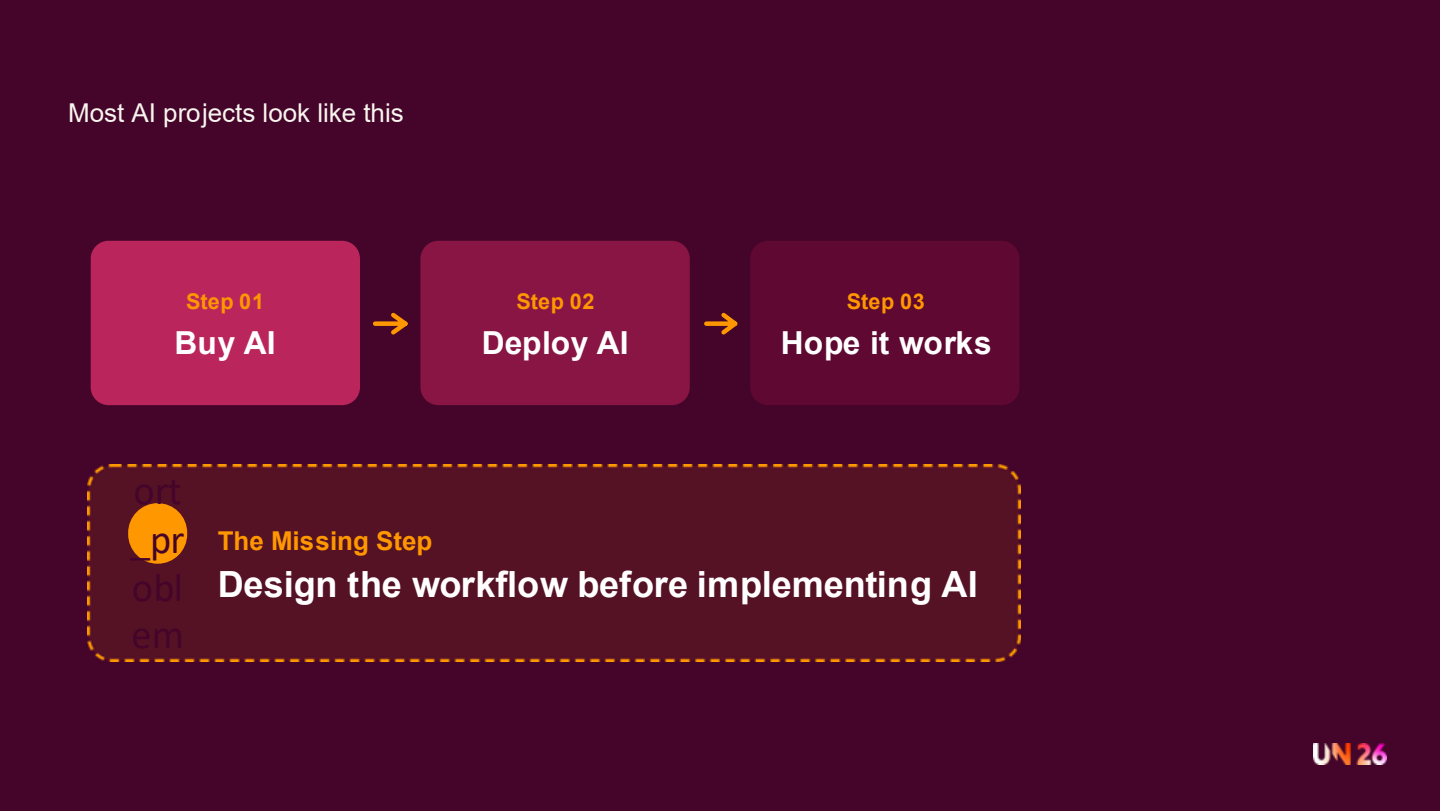
Smith's starting position cuts against most of the current buying conversation. If competitors have access to the same frontier models, the same enrichment sources and broadly the same category of tooling, then the software choice is not the edge. The edge is the thinking that happens before procurement: an explicit, written account of how each recurring task in the sales motion will actually be executed.
She was pointed about the level of granularity required. Workflow-level ambitions — "automate prospecting", "automate outbound" — are too coarse to be operational. A workflow is a bundle of decisions, drafts, judgement calls and pieces of context that live in a rep's head. Until that bundle is unpacked into individual, recurring tasks, no bucket can be assigned and no honest measurement is possible.
"It's not necessarily about what software you buy or what vendor you choose, but more specifically, did you take the time to put together an operating model of exactly how it will be used?"
The failure pattern she described is familiar to anyone who has sat through a renewal review: buy AI, deploy AI, hope it works, and discover twelve months later that it was neither adopted nor effective. The hope step is where the strategy should have been.
Rather than reaching for an anonymised customer horror story, Smith told one against herself. Roughly ten to twelve months earlier, an enterprise SDR on her team bought a personal ChatGPT Enterprise licence and reported significant gains. Within a week, twelve more enterprise SDRs had asked for the same thing. She bought thirteen licences on the spot, with no map and no guidance. In her words, she simply said she trusted them.
Two months later she went back and asked the only questions that matter: how, when and why was the tool being used? The answer was sobering. About half the team had logged in a couple of times and written a handful of emails. Four reps had used it for personal tasks — plant care and cooking recipes among them. Only two had built something genuinely useful and repeatable that a colleague could pick up and reuse.
The lesson she drew was not that the tool was weak or that the reps were unwilling. It was structural: without mapping recurring tasks into the system, there is nothing for ROI to attach itself to. Trust is not a deployment plan. Neither, she added, is an AI policy or a centre-of-excellence team — those arrive too late to fix a problem created at the task level.
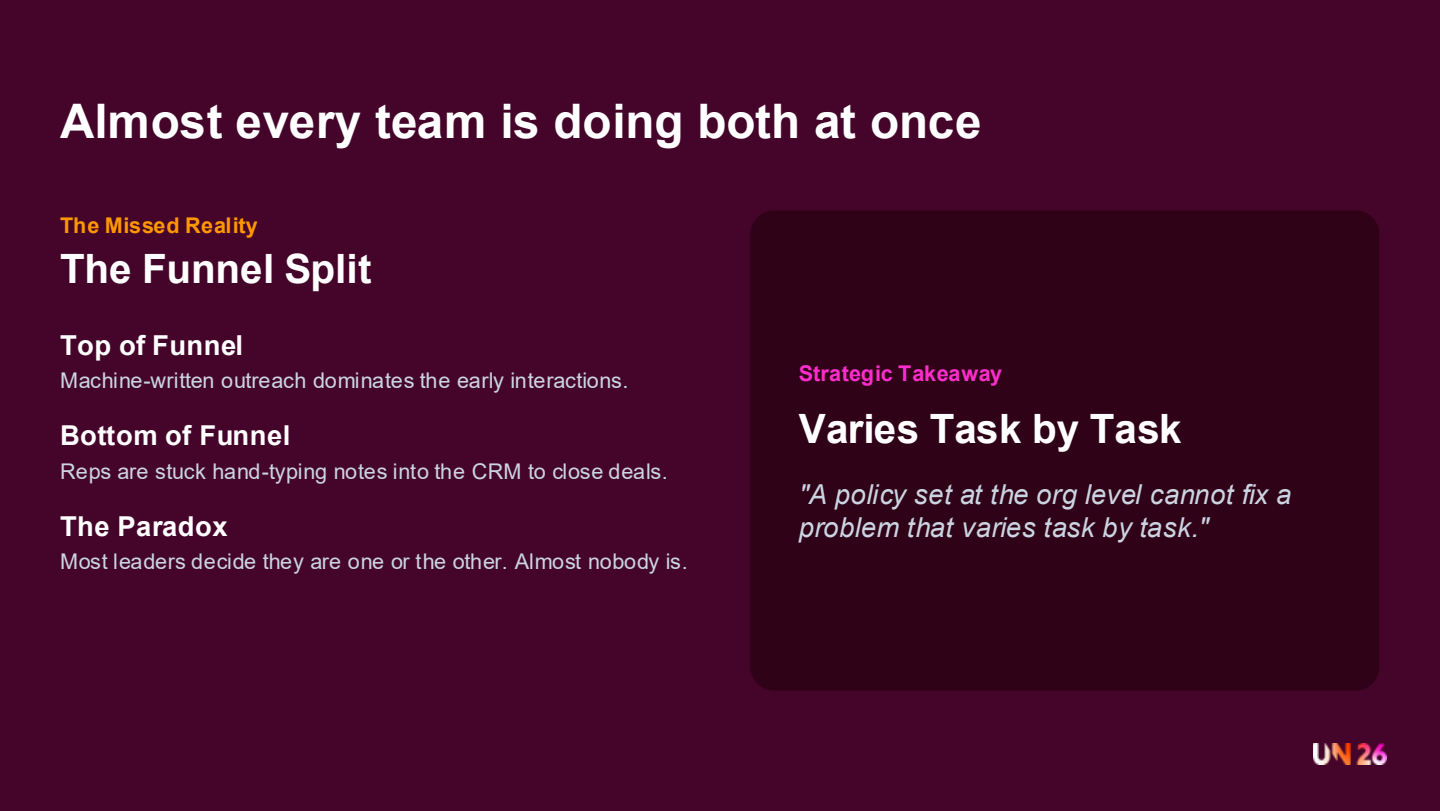
Across customers and peers, Smith sees two distinct failure modes. The first is over-automation. Sales engagement gets fully automated, sends rise tenfold, replies fall, and the sending domain burns. The hyper-"personalised" email references a LinkedIn post the prospect never wrote. But the expensive damage never appears on a dashboard: talent development. If a rep cannot work out for themselves why an account matters, they will not run good discovery either. Capabilities that reps must keep building should not be handed wholesale to a machine.
The second is under-use. The tool is bought, adoption sits around twenty per cent, executives start asking which pipeline and which influenced deals it produced, and reps are still spending most of their week on CRM notes and account research. Asked how, when and why they use it, reps say "I don't know" — which Smith reads bluntly.
"'I don't know' means no."
Her diagnostic is simple: if three reps cannot give a straight answer on how they use a tool, there is a missing piece worth investigating. And the most-missed reality is that teams self-identify as one camp while in practice doing both at once — sometimes inside a single workflow.
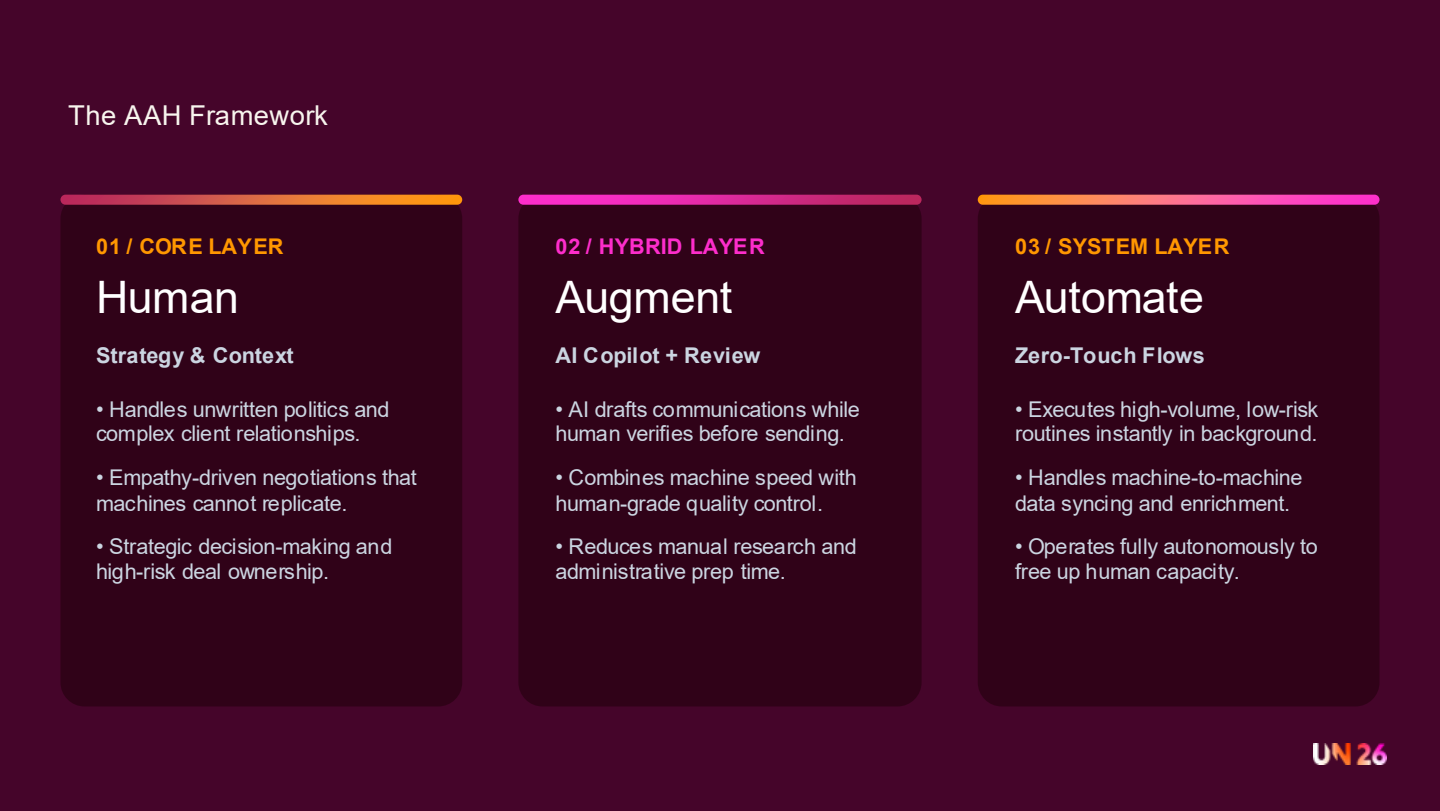
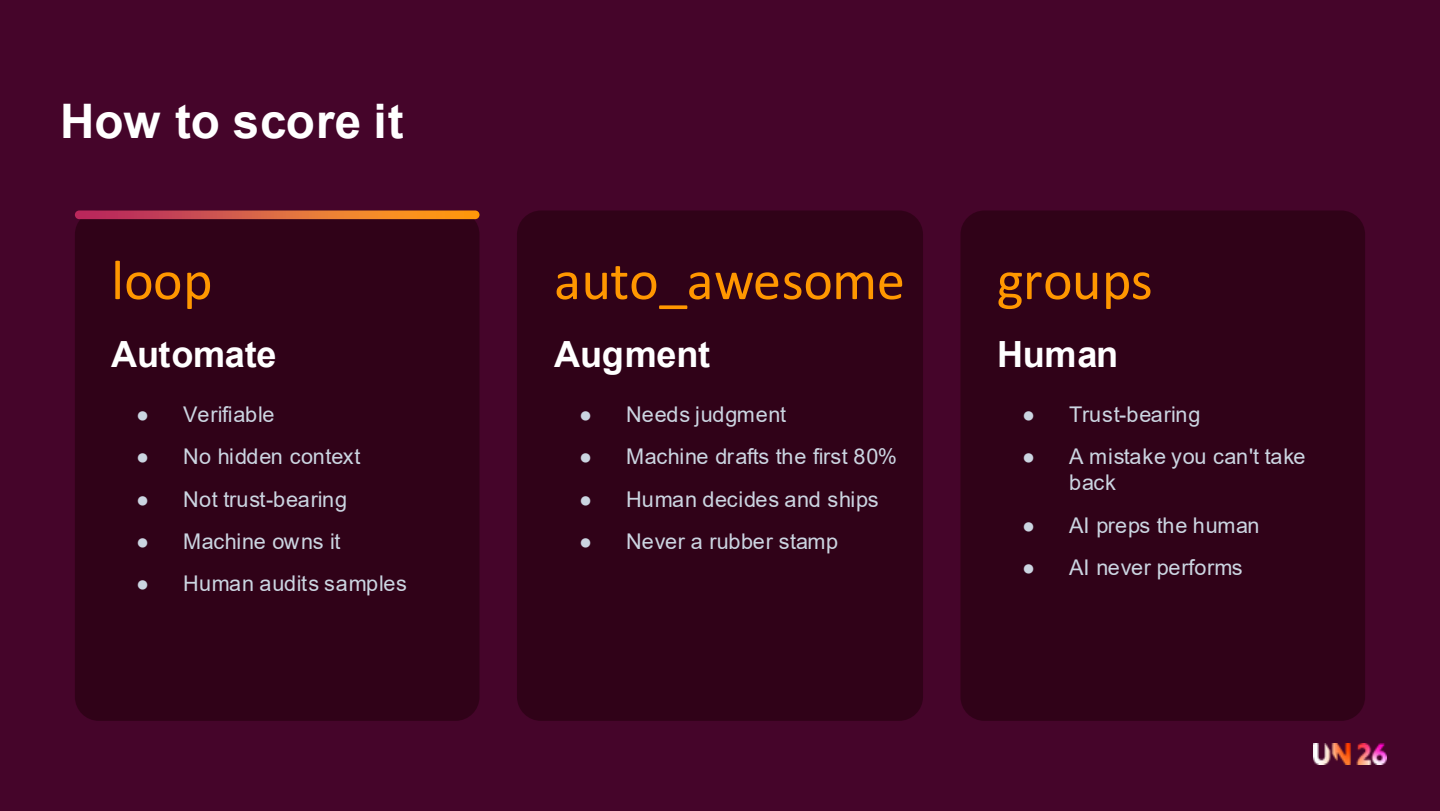
The framework Smith uses is AAH — Automate, Augment, Human — and the rule is that every recurring task in the sales motion sits in exactly one bucket. She positioned this deliberately against the industry's favourite phrase, "human in the loop", which she considers "not specific enough in terms of where the technology has gone". A loop tells you a human is somewhere nearby; it does not tell you who owns the outcome.
Automate means the machine runs the task end to end. A human may audit samples to confirm the model is behaving, but should never review every instance. Augment means the machine does roughly the first eighty per cent and the human decides and ships — the human is always the last step. Human only means the machine must not touch the interaction; it may prepare, but it must not perform. The distinction holds across SDR, AE and AM motions.
She reserved a specific warning for false automation: an automated process with a rubber-stamp "review" tick attached. That is not automation. It signals that the team does not trust the system, and it quietly adds guilt and overhead to someone's day without adding quality. Each task should be consciously assigned, and the system then built for that bucket.
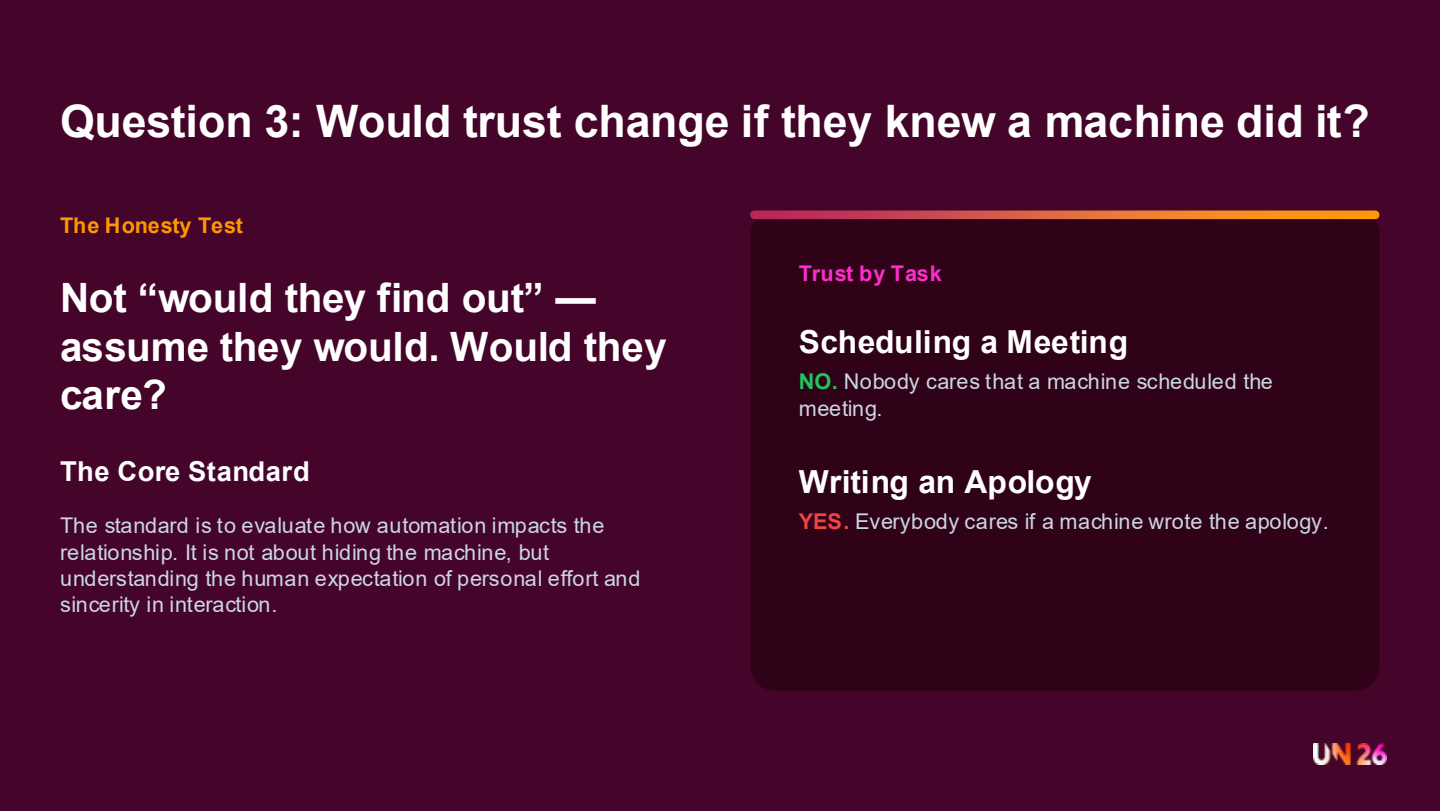
Three questions, asked in order, sort any task into a bucket:
The scoring rules follow directly. Verifiable, no hidden context, not trust-bearing → automate. Hidden context present, but the machine can still draft for the rep to decide and execute → augment. Trust-bearing, or a mistake that cannot be taken back in the relationship → human: the machine preps, it does not perform, and that moment is protected.
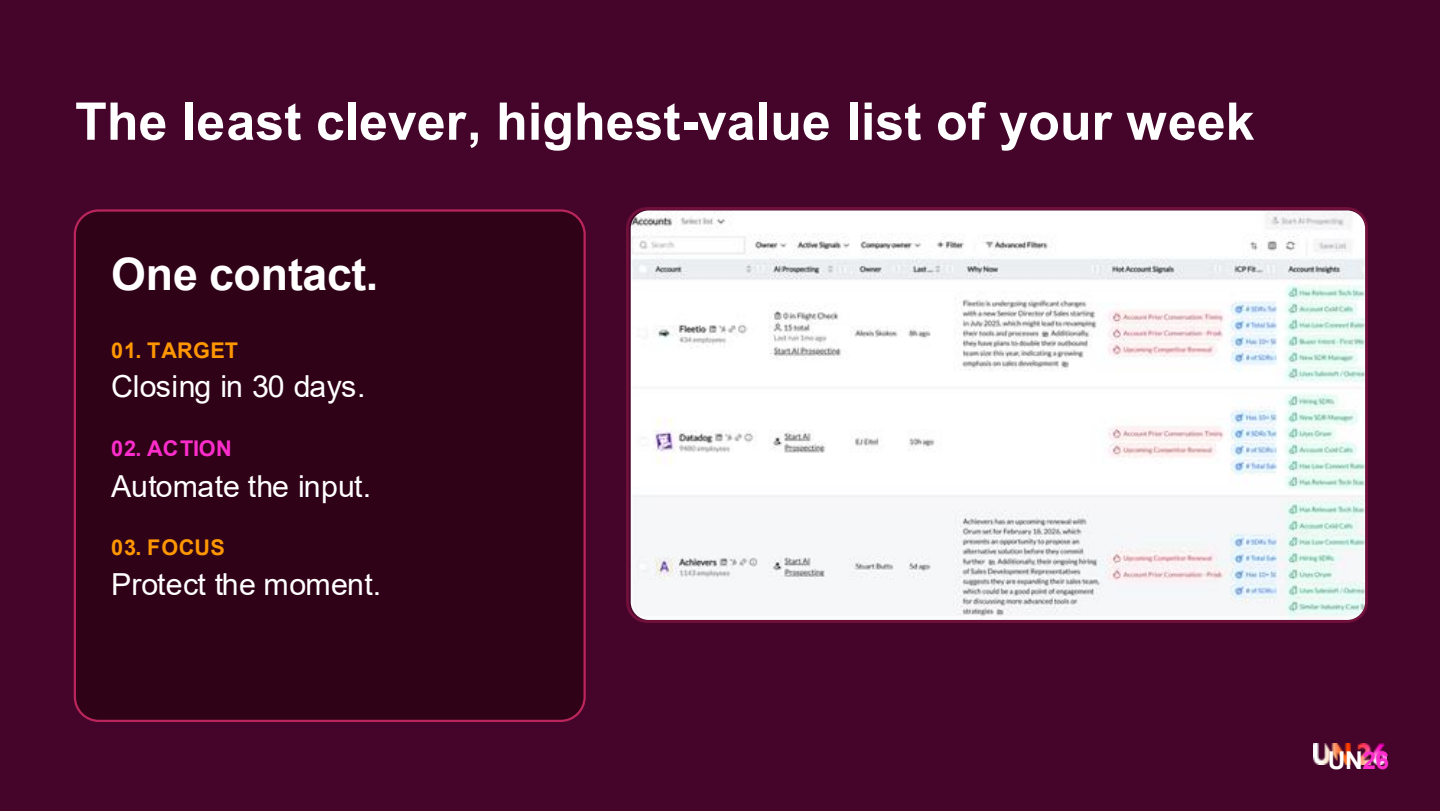
"Automate the input, augment the judgement and decision making, but protect the moment that your reps need to have with their sellers."
Prospecting is Smith's home territory, and she was candid that twelve months ago the easy claim was that you could automate it entirely so reps spend one hundred per cent of their time cold calling. That is unrealistic. Reps still make decisions, tweak emails and retrieve context — a conversation at an event, for instance — that lives outside the system entirely.
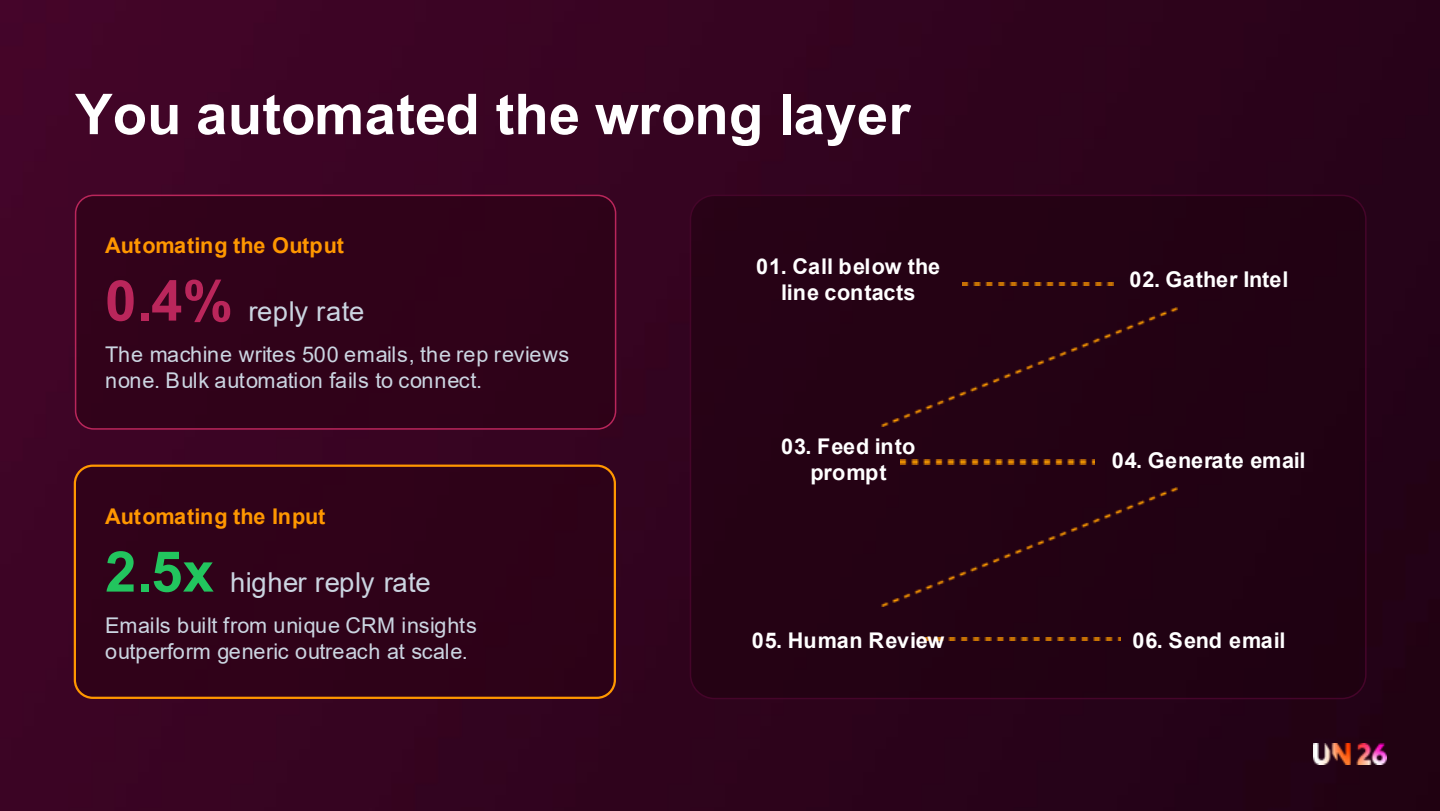
The most common mistake is not simply automating too much. It is automating the wrong layer: the output rather than the input. Mass AI-written emails are the visible result, and they are the slop now filling LinkedIn feeds and inboxes. The correct split inverts it. Automate the input — the account research the system reads and compiles. Augment the email, with a human confirming it actually fits what is known about the account and the prospect.
The worked example made the economics plain. Over-automating produces 500 machine-written emails at a 0.4% reply rate, which is not worth the domain damage. The alternative is 500 automated research briefs, from which the rep writes 40 genuinely contextual emails grounded in real account history — and a far higher response rate. Same hours, same head count, materially better results.
When Smith ran sales engagement through the three questions, she found that nearly everything landing in the automate column was pure administrative overload. Her line on it was unsentimental: there's no craft in typing call notes into a CRM. She admitted she once insisted SDRs hand-write every cold-call note, and now regards that as a waste of time. Systems can listen to calls and draft the notes; the SDR should still review them.
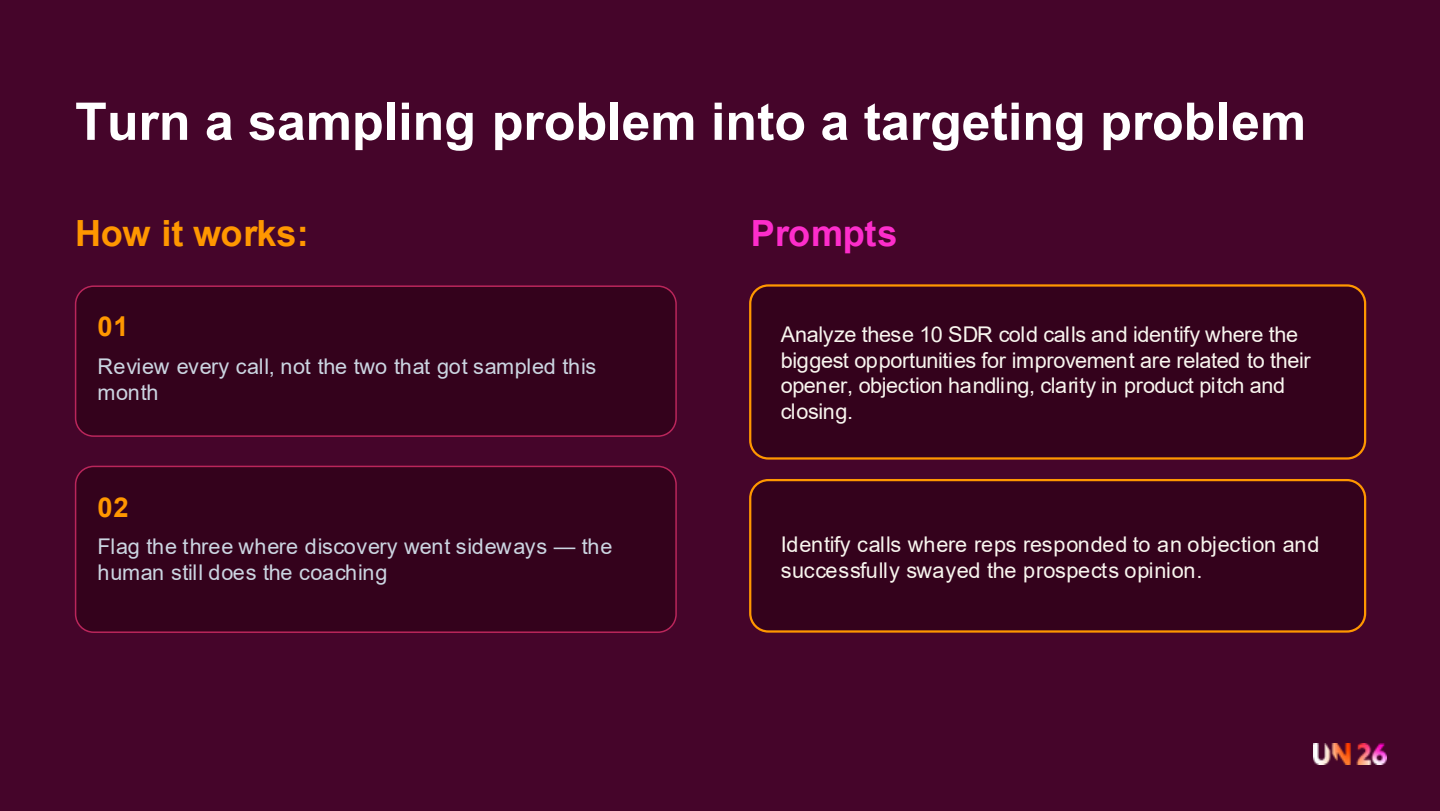
Call scoring, by contrast, belongs firmly in the augment bucket. AI can score every call and surface patterns across a whole team — a genuine shift from spot-checking a handful of recordings to seeing the full distribution. What AI cannot do is coach. Every rep receives feedback differently, and the calibration between directness and softness is a human judgement. The manager still delivers the coaching and builds the development plan; the tooling, Nooks included, does the scoring.
She also flagged that the right split varies by motion. Enterprise and SMB teams will not land on the same map, and volume changes the maths. The most common failure remains doing both at once — over-automating some tasks while under-automating others, and frequently just switching platforms rather than changing the work itself.
Late-stage deal management for AEs and AMs is the clearest case in the framework, because all three questions come back negative at once. You cannot verify the work before the buyer feels it. It depends on unwritten context accumulated through small interactions, not just call transcripts. And trust is the entire asset — as Smith put it, people buy from people they trust; if they didn't, there wouldn't be salespeople. Buyer interactions at this stage should not be automated.
That does not leave the machine idle. Its job becomes prep and surfacing: what was shared the last time this prospect evaluated you, or a leadership change on LinkedIn the rep has not yet spotted. The principle she repeated — prep your AE before they walk into a meeting, but protect the moment — draws the line precisely where the relationship begins.
Her internal example at Nooks was deliberately unglamorous: query every deal that has only one contact attached and a close date inside the next 30 or 60 days, matched to your actual deal cycle, and use that list to decide where the month or the quarter gets spent. The machine cannot make the second outreach or loop in the missing stakeholders — those are human acts. What it can do is direct where human time goes.
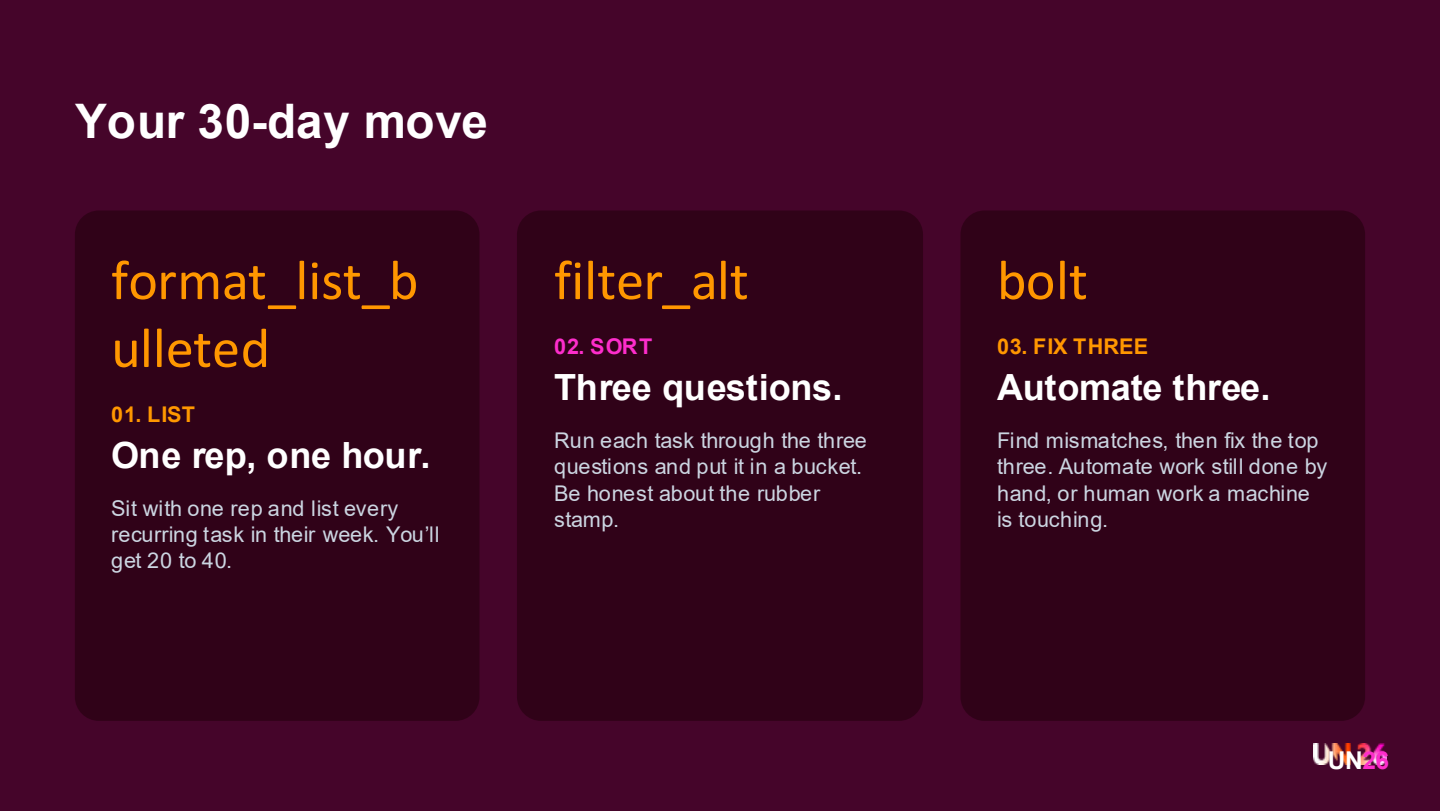
Smith closed by making the work deliberately small, on the grounds that everyone in the room already has a full-time job on top of working out where AI fits. Her explicit instruction was not to build a strategy or convene a working group. The whole exercise is scoped to an afternoon, including roughly one hour sitting with a rep.
Then compare the map against what is actually happening — including how reps are really using the technology you have already bought. Most teams find their automation candidates are "embarrassingly obvious" once mapped. The genuine value is in the mismatches: tasks assumed to be automatable that turn out to need augmenting instead. Outbound email was her worked example; not all of it should be automated, and some of it should be switched back.
"If you have a list of 20 to 40, choose three."
Three — the easiest and most obvious. Not a quarterly programme, not an annual transformation. She was firm that things need to be bite-sized and not simply added to a list, and she invited attendees to photograph the three-questions slide and revisit any purchased technology with poor adoption, or any tool currently under evaluation, against the bucket model. Her own caveat was honest: the exercise will not solve everything, but it is a good first step.
One question was taken at the close, on feedback loops: how should teams know whether the automate/augment split is working?
Smith's answer was that it depends on what is being automated versus augmented and on the technology already in place — some tools have good native reporting and others do not. Her firm position was that a feedback loop should always exist both before and after a change, so there is a baseline to compare against rather than a retrospective guess.
On A/B testing specifically, she noted that team size is the constraint. With a team of around forty reps, some can trial one approach while others trial the alternative, and the comparison is meaningful. Smaller teams need different mechanics. There are several ways to operationalise it, and she invited attendees with further questions to continue the conversation at the booths downstairs.
She also left one question deliberately open, directed at people leaders rather than the room's tooling decisions: what AI is doing to the next generation of salespeople if everything — or nothing — is automated. ROI measurement was explicitly deferred and not covered in this session.